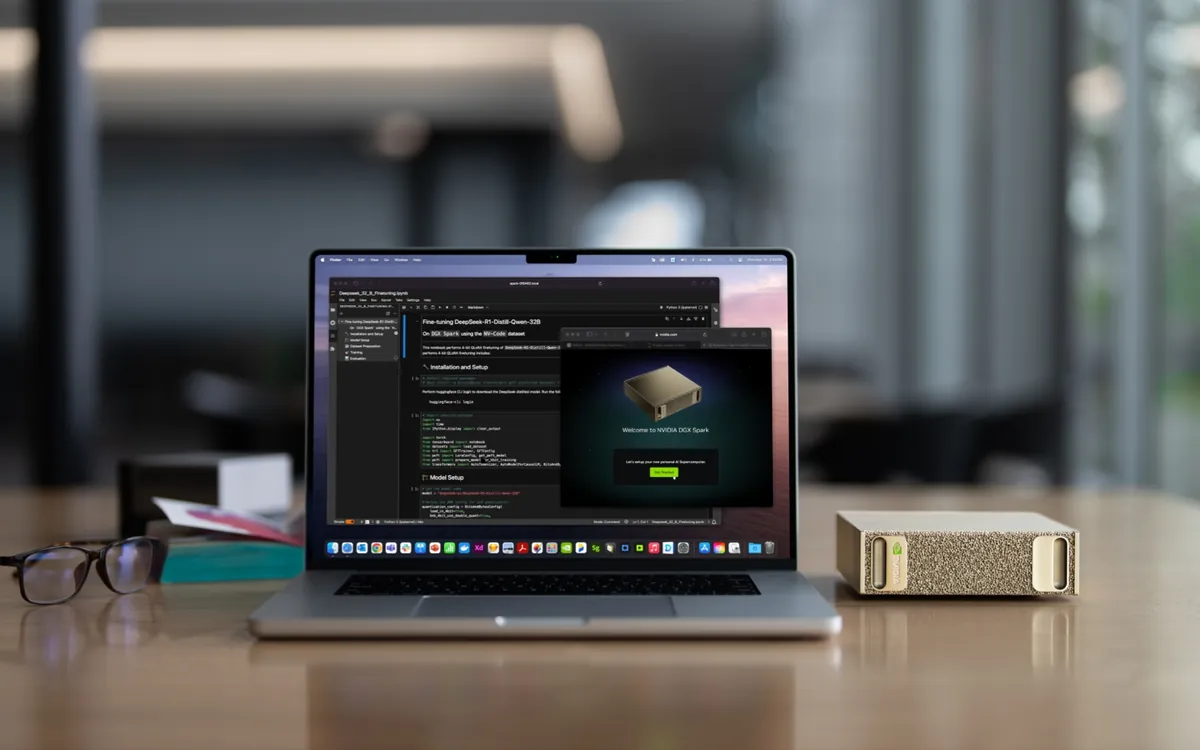
NVIDIA DGX Spark
128 GB of memory. Large models run on a desk, no server room.
The model runs on hardware in your company. Your data never leaves your network and you do not pay per request.
Sensitive documents, contracts, health or financial data stay inside the company. The model works without an internet connection, runs at a steady speed and you stay in full control of operation.
We size the machine to the model and the number of users. From a small desktop computer through a GPU server to a rented VPS.
128 GB of memory. Large models run on a desk, no server room.
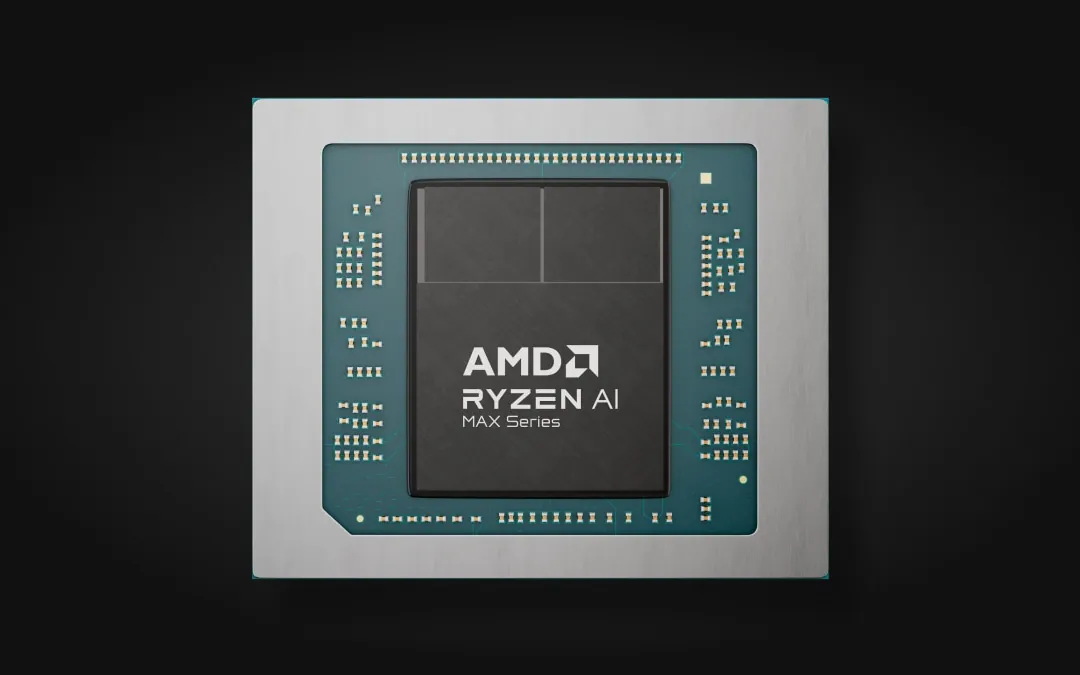
Up to 128 GB of shared memory in a quiet machine for a small team.
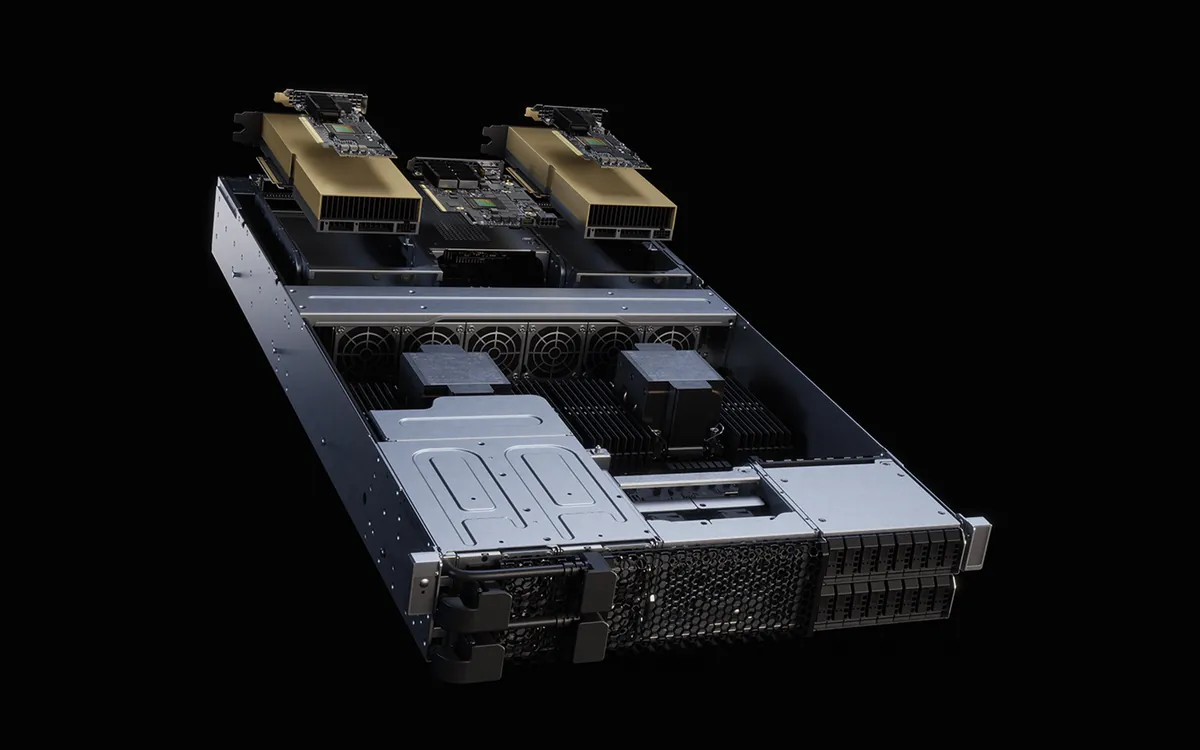
From RTX PRO 6000 to HGX B200. For large models and many users.
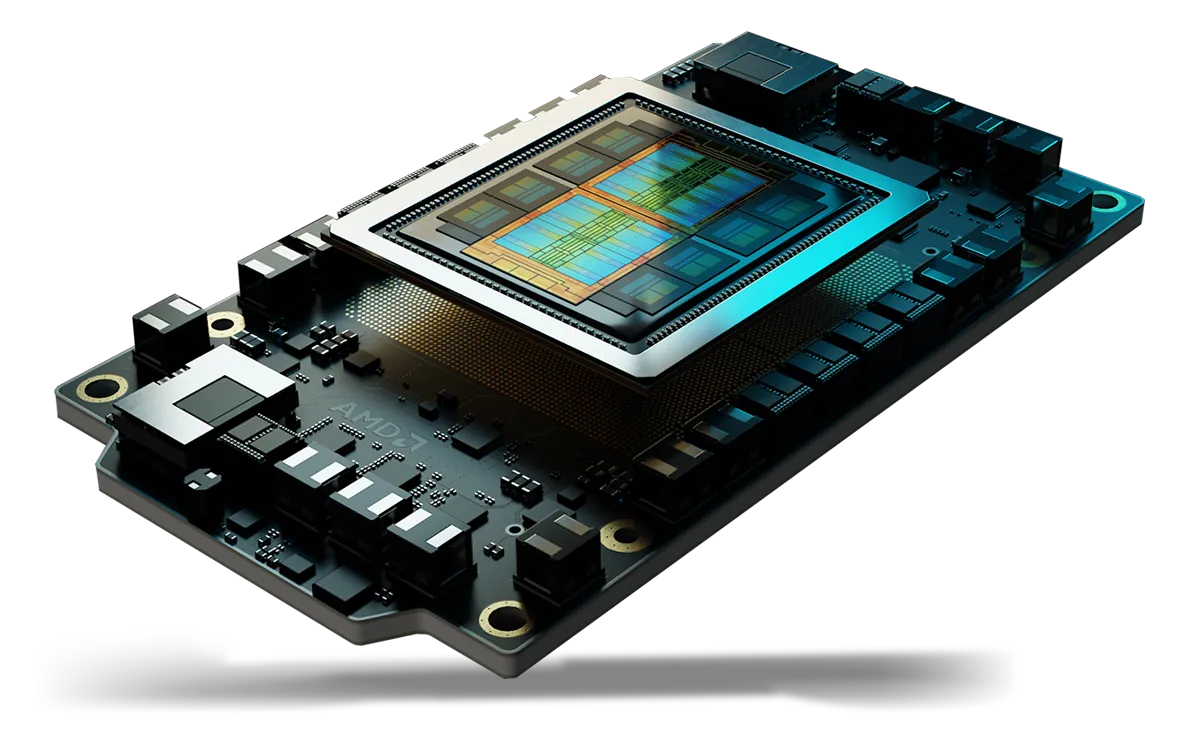
MI350 cards with 288 GB of HBM3E memory. Open ROCm software.
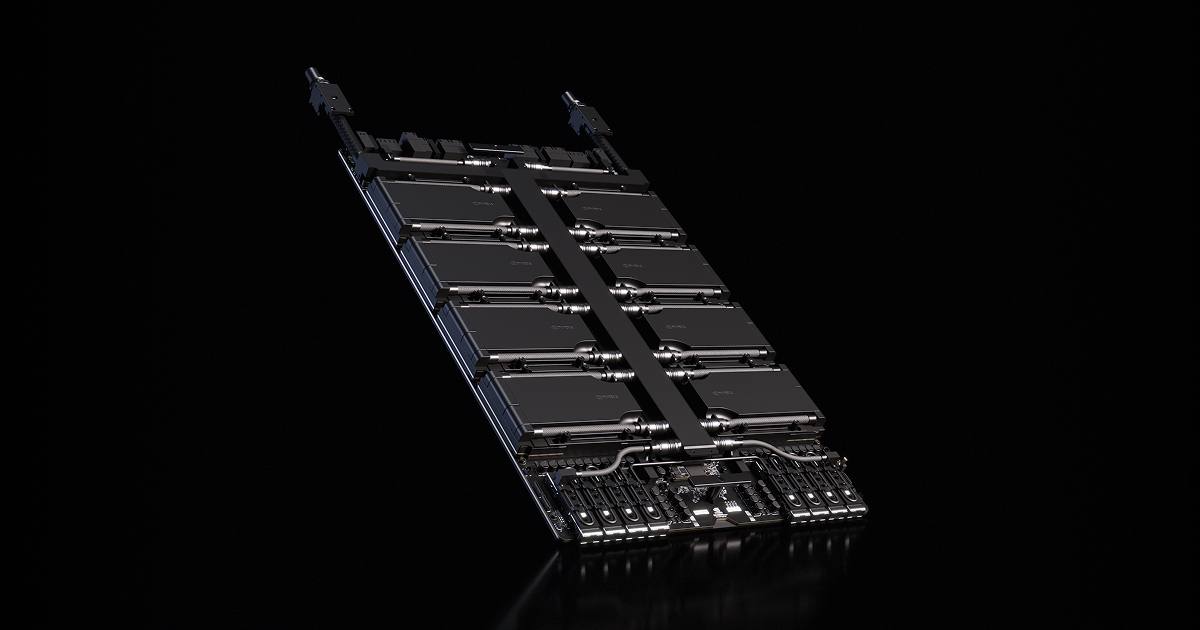
A rented virtual server with a GPU. No hardware to buy, the model runs on capacity reserved for you.
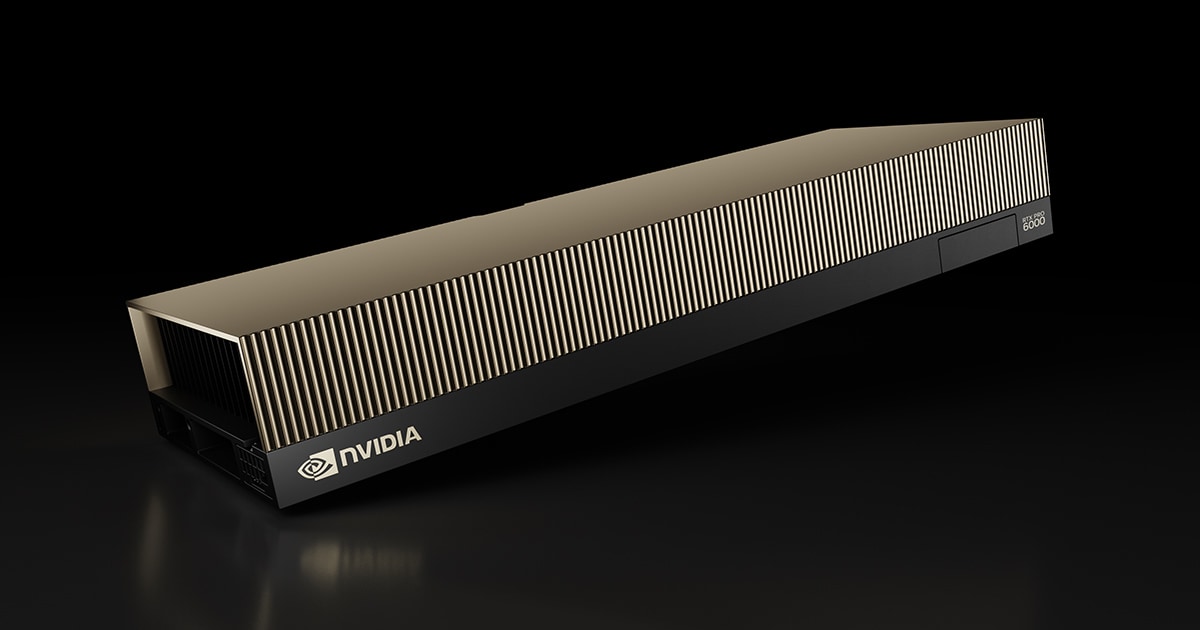
A whole physical GPU server in a data centre. Full control, steady performance, your data on a machine that is yours alone.
Coding and assistant tools, known as harnesses, connect to a model running on your side. These are our best picks.
Our own CLI, built for local and cloud models.
 OpenCode
An open agent that connects to a model running on your side as well as to cloud providers.
 Hermes
Nous Research's agent, independent of any one provider.
 OpenClaw
A personal AI assistant running on your own devices.
 Qwen CodeOfficial tool
The Qwen team's official open-source terminal agent (Apache 2.0).
 Mistral VibeOfficial tool
Mistral's open-source terminal agent (Apache 2.0), released with the Devstral 2 models.
We match the model and hardware to your data, team and budget.
We supply and configure the machine, access and the link to your tools.
We test it on a real task and train your team.
Tell us what you need. We will recommend a setup, or another way of running it if it fits better.
Write a few lines about what you do. We reply the same day and book twenty minutes on the phone.
Tap a photo to see the contact.
Websites, SEO, AEO, AI infrastructure project manager, 3D modeling, software development
774 915 200 aetheron@aetheron.czPrague